
Quick answer
To restore your website safely, start with a verified backup from before the problem and recover only the affected files or database. Test the website restore in a separate location before replacing the live site. Protect newer orders, inquiries and messages while planning recovery.
Choose the right website restore
- One file was deleted: check File Manager Trash first, then inspect a backup of the exact file. Follow the deleted-file recovery steps below.
- A WordPress site is broken: confirm the backup contains the matching files and database. Restoring files alone may leave broken content or settings.
- New orders or inquiries arrived after the backup: plan how to preserve that newer data before a database replacement.
- You have a full cPanel account archive or an uncertain recovery target: contact support for the supported restore procedure. Include the affected domain, backup date, exact problem and intended recovery scope, with private details redacted.
Before you begin
Choose an approved backup and a separate recovery location. Confirm enough storage, access controls, and a plan for handling any personal information in the restored data.
What to do
- Record the backup identity and integrity information before extracting it. Confirm that the recovery target is separate from the live document root and database.
- Restore files and database according to the platform procedure. Update only the environment-specific settings required for the isolated copy.
- Protect the restored site and disable outbound mail, payments, scheduled jobs, and live integrations before browsing workflows that might trigger them.
- Check representative pages, media, administration, and required application functions. Record missing files, incompatible versions, or unavailable external dependencies.
- Document the recovery steps, time required, and test results. Retire or retain the test copy according to the agreed data-retention policy.
Practice with a harmless static-file archive
Use this small exercise to learn the file controls before attempting a real recovery. It tests files only. A WordPress or other database application also needs its database, configuration and application checks.
- Create a clearly named practice folder outside the live document root. Add only sample HTML, CSS and a harmless hidden text file. Keep credentials and real customer records out of the exercise.
- In File Manager, select the sample files, choose Compress, select Zip Archive and give the archive a recognizable name. Check the completion results.
- Download the ZIP and check that it opens and contains exactly the intended files, including any expected hidden file. Keep an independent copy before attempting recovery.
- In File Manager, select the ZIP and choose Extract. Change the destination to a new, empty practice subfolder. Read the whole destination before selecting Extract Files; do not extract over the live website.
- Check the extraction results and open the separate recovered folder. Download the recovered files and compare their contents or SHA256 hashes with the originals. A file listing by itself does not prove matching contents.
- Preview the recovered static pages in an isolated local environment. Test a direct nested-page load, relative links and styles. Keep the archive and results private; do not treat this exercise as a full-account or database restore.
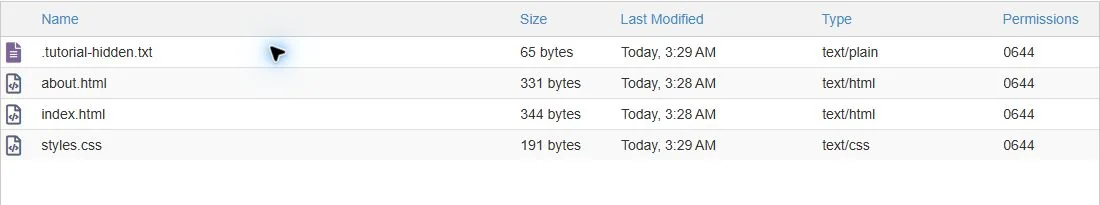
Recovered demonstration files in a separate folder outside the live document root. Each recovered file was independently compared with its original and matched exactly. This proves this small static-file recovery example; it does not certify a WordPress database or a full-account restore.
How to check the result
A restore passes when the agreed website functions can be used and important data is present. Distinguish an extracted archive from a tested application and note anything that required manual intervention.
If you need help
If the copy fails, preserve the error and backup identity rather than overwriting the original archive. Ask whether configuration, versions, encryption keys, or external services are missing from the documented recovery process.
Restore deleted website files with the smallest safe scope
- Confirm the affected domain and path and preserve the current state. If the item was deleted through File Manager and Trash has not been emptied, open Files > File Manager > View Trash.
- Select the exact file or folder and review its intended destination before choosing Restore and confirming. Check whether a newer item already exists there. Trash recovery is unavailable when the item was permanently removed or deleted by a different process that did not retain it.
- If the item is absent from Trash, identify a known good backup and its time. Recover only the required item into a separate nonpublic location for inspection before a deliberate replacement. For a provider-managed or full-account archive, ask support to confirm the supported recovery method.
- Reopen the affected HTTPS page and check the related image, asset or application function. For a database-backed feature, a restored file alone may not recover its content. Record any unverified functions and keep the original backup.
Restore failed: preserve the error and current data
Record the backup identity, archive type, target path/database, exact error and time/time zone. A complete full-account archive may need the provider's restore process; a partial upload control is not interchangeable. Check storage and compatibility with support before retrying. If the problem followed a suspected compromise, preserve the evidence and request an incident review before restoring an uncertain backup.
Ask support for recovery help before a live overwrite when the backup scope, ownership, current data or safe destination is unclear. This guide describes recovery choices; it does not establish that your particular backup has passed an application test.
Related help
- Check that a WordPress backup includes files and database
- Preserve new orders and inquiries when planning a restore
- Store website backups outside public web access
- How to backup your website in cPanel
- Send a website support request with useful troubleshooting details
Official references
Reviewed October 31, 2026. Interfaces, vendor availability, and account features can change. Check your current account before making changes.
Customer troubleshooting and related-help review: November 1, 2026. Earlier review notes retain their original scope.
Recovery decision steps and related links reviewed November 2, 2026. The earlier static-file exercise retains its stated scope.
